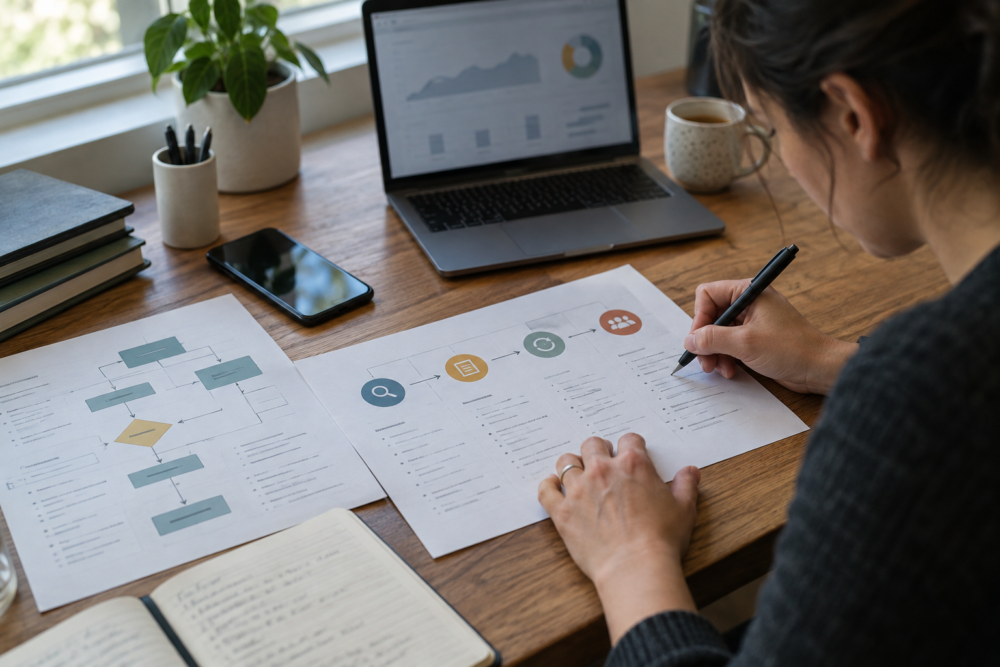
A practical runbook for detecting, assessing, retrying, and escalating API integration failures without creating duplicate work or leaving a team guessing.

A practical guide to running a calm, focused incident-response tabletop exercise that clarifies roles, decisions, communication, and follow-up work.
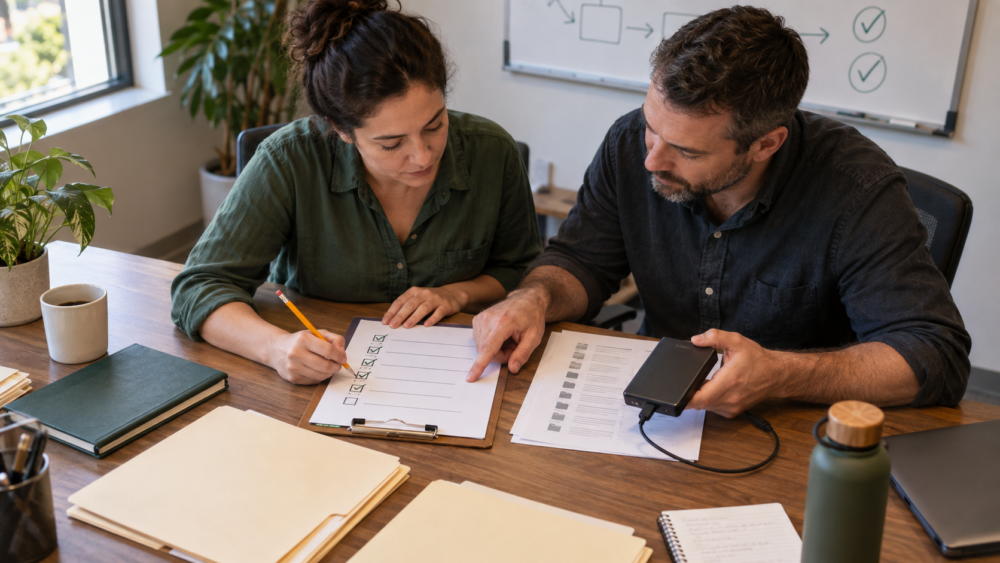
A practical restore-test plan for small businesses that need to verify backup integrity, recovery steps, and who does what when systems are unavailable.
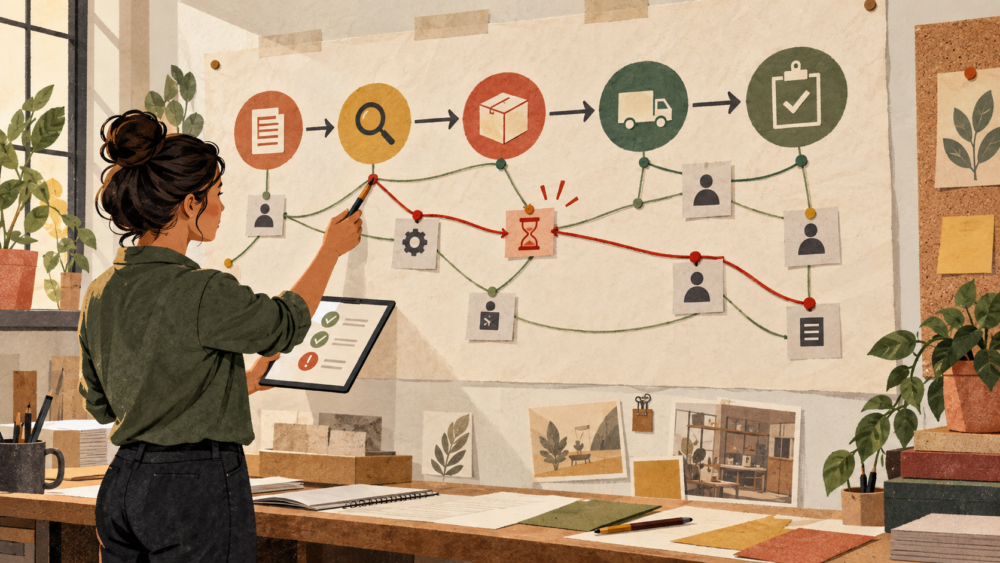
A practical guide to measuring automated workflows so teams can find failures, explain outcomes, and improve the right step before adding more complexity.
A practical guide to using idempotency keys, stable request identities, and reconciliation checks to make business integrations safer when networks fail.
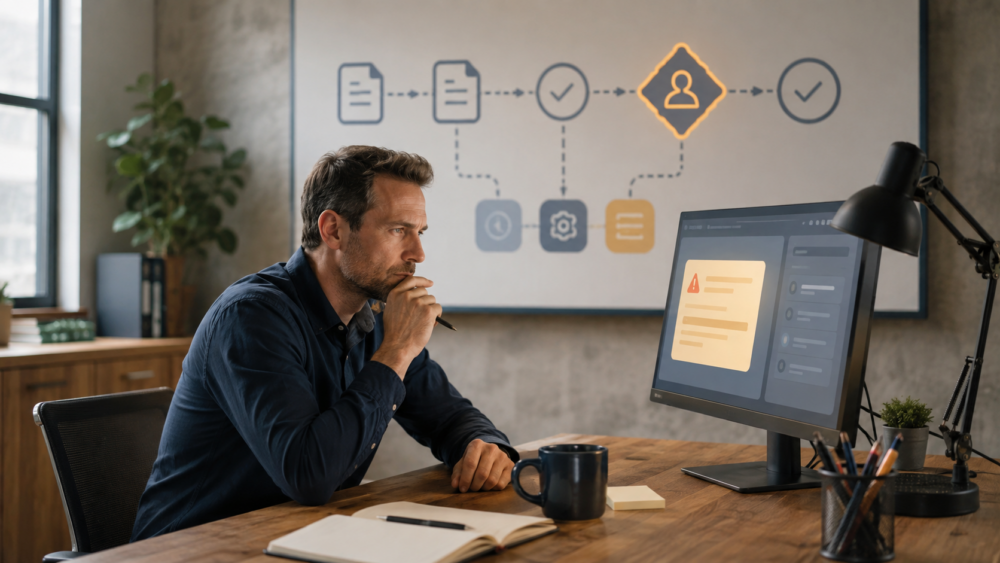
Learn where to pause an automated workflow, what reviewers need to see, and how to make exceptions useful instead of disruptive.
A practical guide to using queues to absorb bursts, isolate failures, and give people a clear path for reviewing exceptions.
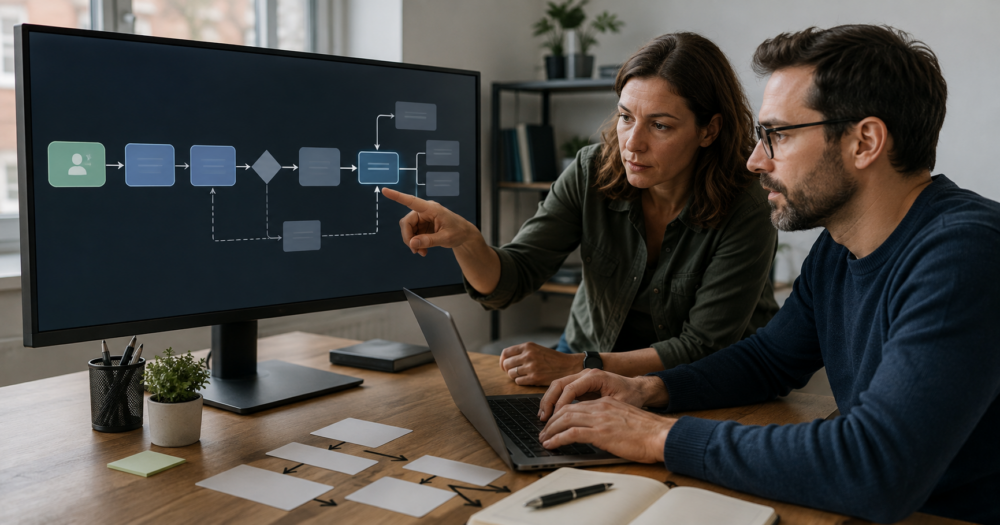
A practical pattern for making business-system integrations more dependable when requests fail, repeat, or return unexpected data.
A lightweight checklist helps small teams release changes to internal applications with clearer ownership, useful verification, and a workable recovery path.
An API connection needs an operational owner after launch. Use this practical ownership model to make exceptions, changes, and routine checks manageable.