A practical guide to choosing reliability measures for internal applications, setting realistic targets, and turning monitoring into useful decisions.
A practical maintenance model for keeping a custom business application reliable, understandable, and ready to recover after launch.
A practical guide to documenting the repeatable checks, decisions, and recovery steps that help small teams support critical software with less guesswork.
A practical release checklist for deciding what to monitor, how to limit exposure, and when to roll back or move forward safely.
A practical guide to choosing useful application health signals, separating dashboards from alerts, and giving a small team enough context to respond well.
A practical production-readiness review helps a small team confirm that a custom application can be operated, supported, and recovered before real users depend on it.
Feature flags can separate deploying code from exposing a change. Learn how small teams can use staged rollouts, clear ownership, and rollback plans without creating configuration chaos.
A practical restore-test plan for small businesses that need to verify backup integrity, recovery steps, and who does what when systems are unavailable.
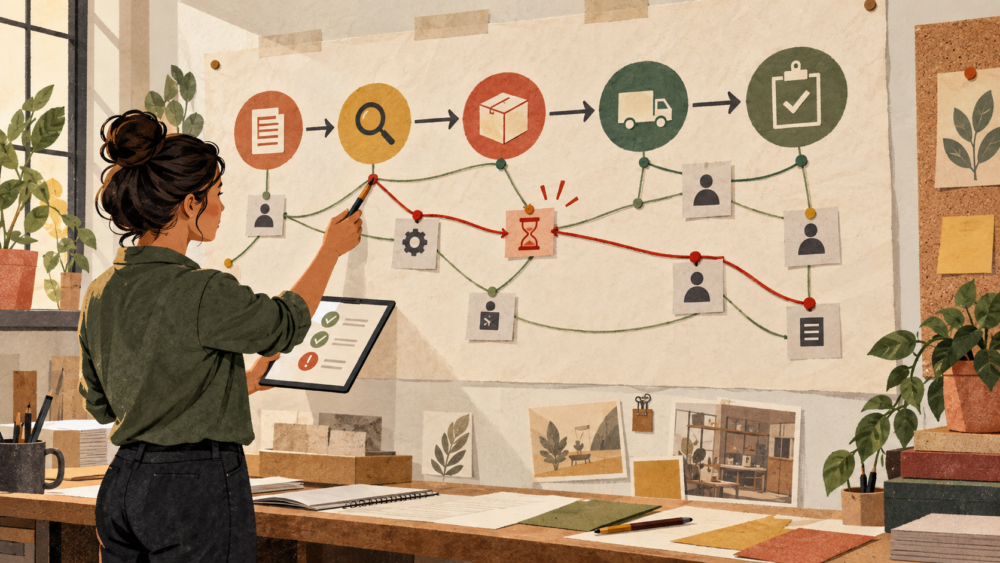
A practical guide to measuring automated workflows so teams can find failures, explain outcomes, and improve the right step before adding more complexity.
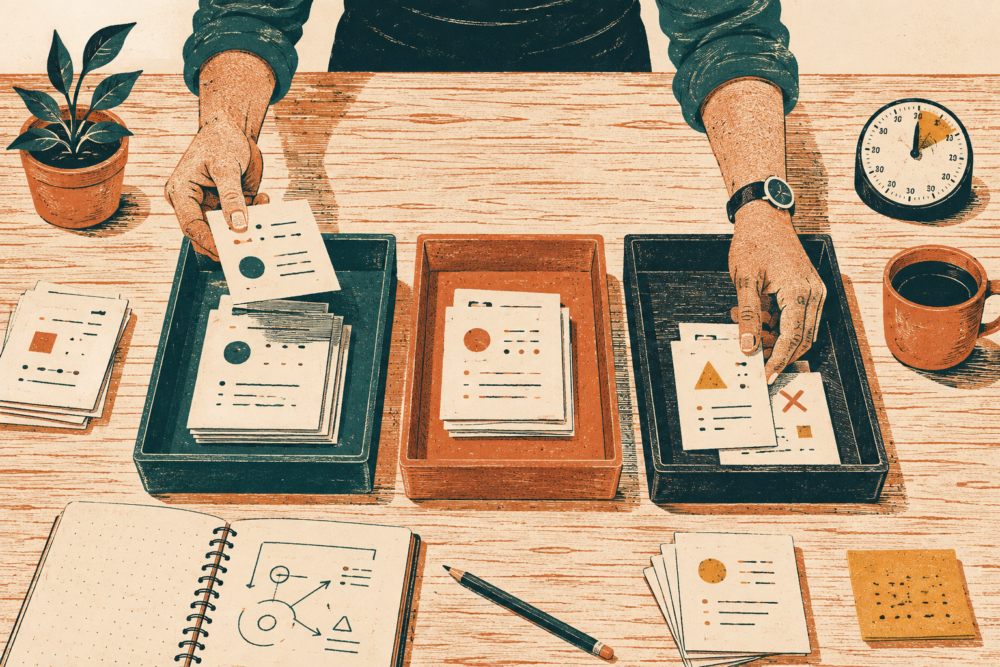
A practical guide to using queues to absorb bursts, isolate failures, and give people a clear path for reviewing exceptions.